Machine learning algorithms to infer trait-matching and predict species interactions in ecological networks
Abstract
Ecologists have long suspected that species are more likely to interact if their traits match in a particular way. For example, a pollination interaction may be more likely if the proportions of a bee's tongue fit a plant's flower shape. Empirical estimates of the importance of trait‐matching for determining species interactions, however, vary significantly among different types of ecological networks. Here, we show that ambiguity among empirical trait‐matching studies may have arisen at least in parts from using overly simple statistical models. Using simulated and real data, we contrast conventional generalized linear models (GLM) with more flexible Machine Learning (ML) models (Random Forest, Boosted Regression Trees, Deep Neural Networks, Convolutional Neural Networks, Support Vector Machines, naïve Bayes, and k‐Nearest‐Neighbor), testing their ability to predict species interactions based on traits, and infer trait combinations causally responsible for species interactions. We found that the best ML models can successfully predict species interactions in plant–pollinator networks, outperforming GLMs by a substantial margin. Our results also demonstrate that ML models can better identify the causally responsible trait‐matching combinations than GLMs. In two case studies, the best ML models successfully predicted species interactions in a global plant–pollinator database and inferred ecologically plausible trait‐matching rules for a plant–hummingbird network from Costa Rica, without any prior assumptions about the system. We conclude that flexible ML models offer many advantages over traditional regression models for understanding interaction networks. We anticipate that these results extrapolate to other ecological network types. More generally, our results highlight the potential of machine learning and artificial intelligence for inference in ecology, beyond standard tasks such as image or pattern recognition.
What the paper shows and why it matters
(AI-generated)
Ecologists suspect that species interact when their traits fit together, for example a bee’s tongue and a flower’s shape (trait-matching). Estimates of how much it matters vary widely between network types, and predicting interactions from traits has often worked only moderately. Most studies used conventional regression models such as generalised linear models (GLMs), with trait combinations specified in advance, or phylogenetic proxies for traits. Such models are interpretable, and a few trait axes often explain a network’s structure (Eklöf et al. 2013). But they may be too rigid for how traits give rise to interactions. Flexible machine-learning methods had predicted food-web links (Desjardins-Proulx et al. 2017), yet, to the authors’ knowledge, it had not been shown that they can also reveal which trait combinations are responsible. The paper questions the assumption that simple regression models are adequate for inferring trait-matching.
The paper argues that the mixed evidence on trait-matching in species-interaction networks may partly reflect overly simple statistical models: the best flexible machine-learning models predict interactions from traits, and identify the responsible trait pairs, better than regression does in simulations. In simulated plant–pollinator networks, random forests, boosted regression trees and deep neural networks reached a true skill statistic (0 is chance, 1 perfect) of 0.61–0.63, against 0.41 for GLMs. The H-statistic, a measure of how strongly a model’s predictions depend on two traits jointly, recovered on average 70–80% of the true trait pairs for presence-absence data. The accuracy of GLMs in identifying pairs fell most as more pairs mattered. In two real data sets, random forests predicted crop–pollinator interactions best (AUC 0.73, where 0.5 is chance and 1 perfect), and in Costa Rican plant–hummingbird networks the models singled out corolla length matched with bill length, among the strongest, ecologically plausible pairs, without prior assumptions.
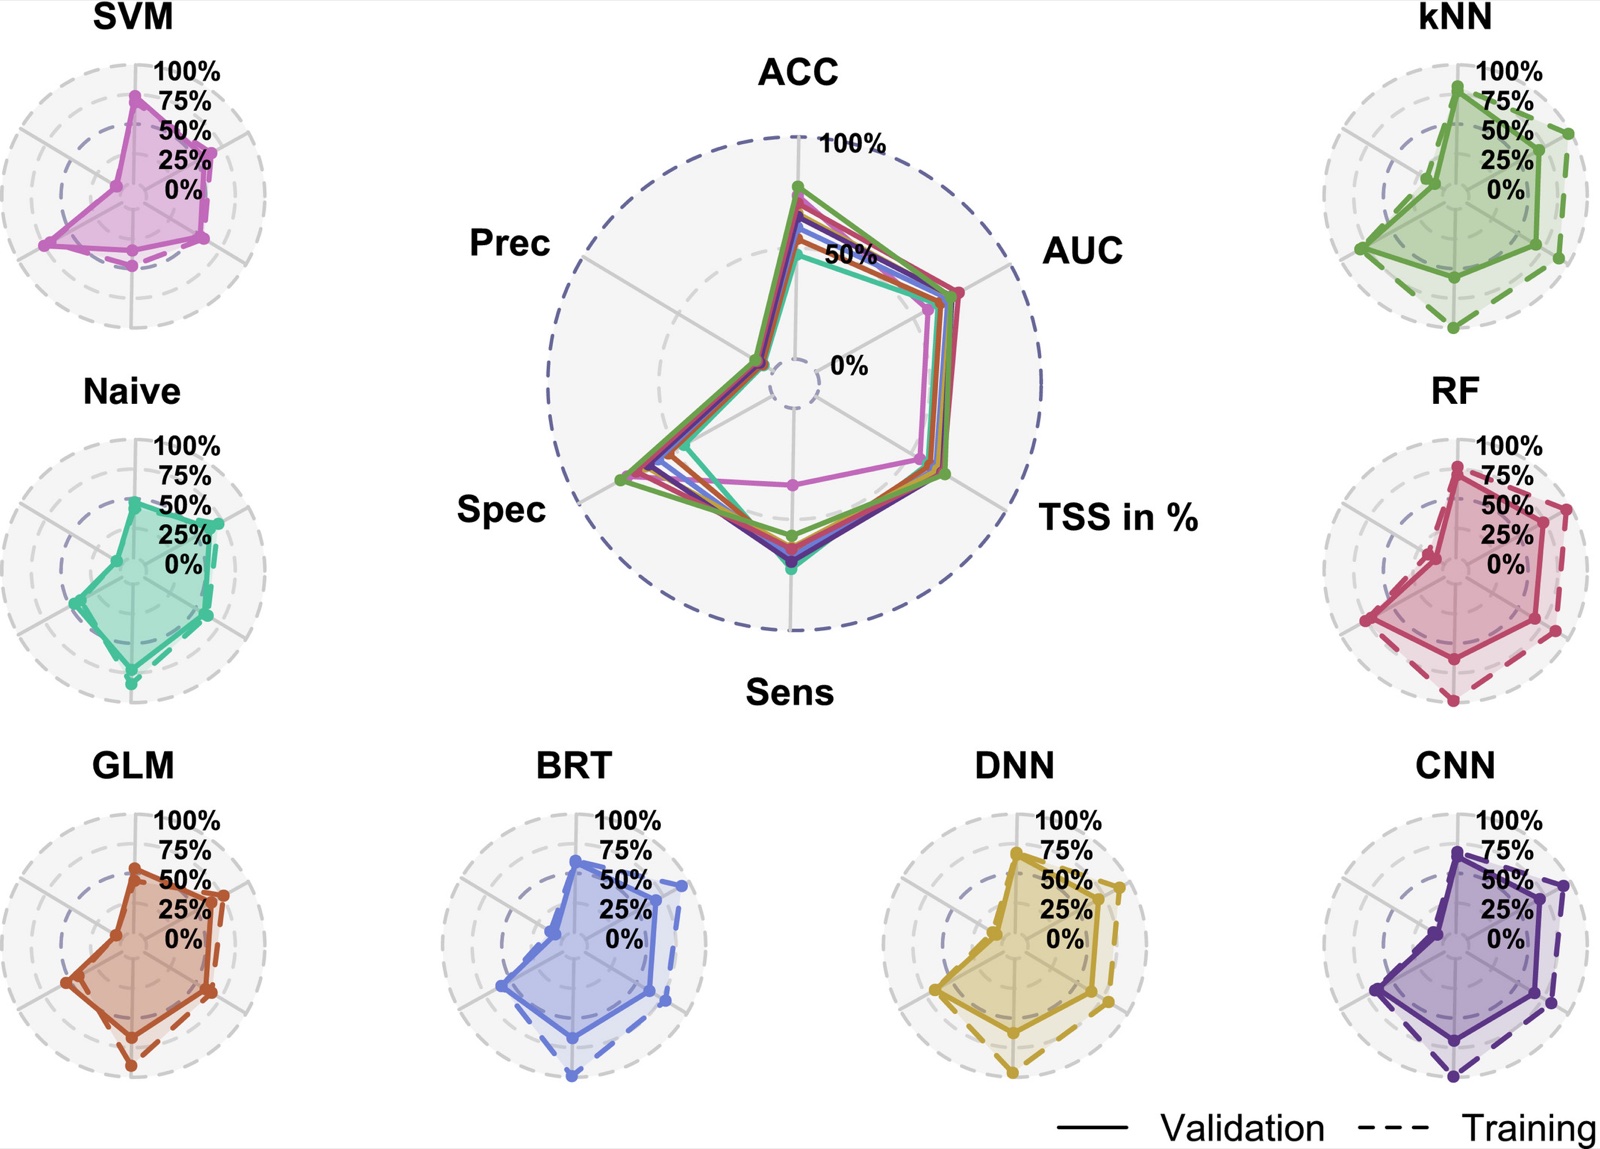
The study speculates that earlier GLM-based work may have considerably underestimated trait-matching, unless only one or two trait pairs dominate a network. It offers flexible models plus interpretation tools as a way to infer, not only predict, how traits shape interaction networks. The H-statistic is, however, computationally expensive and sensitive to correlated traits. A later study (Van Kleunen et al. 2026) built on this and other flexible-model approaches to trait-matching to predict missing links in food webs.
References
- Eklöf et al. (2013). The dimensionality of ecological networks. Ecology Letters 16, 577–583. doi:10.1111/ele.12081
- Desjardins-Proulx et al. (2017). Ecological interactions and the Netflix problem. PeerJ 5, e3644. doi:10.7717/peerj.3644
- Van Kleunen et al. (2026). Predicting missing links in food webs using stacked models and species traits. Nature Communications 17, 2298. doi:10.1038/s41467-026-68769-7