Towards robust statistical inference for complex computer models
Abstract
Ecologists increasingly rely on complex computer simulations to forecast ecological systems. To make such forecasts precise, uncertainties in model parameters and structure must be reduced and correctly propagated to model outputs. Naively using standard statistical techniques for this task, however, can lead to bias and underestimation of uncertainties in parameters and predictions. Here, we explain why these problems occur and propose a framework for robust inference with complex computer simulations. After having identified that model error is more consequential in complex computer simulations, due to their more pronounced nonlinearity and interconnectedness, we discuss as possible solutions data rebalancing and adding bias corrections on model outputs or processes during or after the calibration procedure. We illustrate the methods in a case study, using a dynamic vegetation model. We conclude that developing better methods for robust inference of complex computer simulations is vital for generating reliable predictions of ecosystem responses.
What the paper shows and why it matters
(AI-generated)
Ecologists increasingly use complex computer simulations, such as process-based models of forests, to forecast ecosystem change, and forecasts are only as useful for decisions as their parameters and uncertainty estimates are reliable. The field has moved from informal tuning to statistical calibration by maximum likelihood or Bayesian inference, which looks no different from fitting a regression model. These methods, however, estimate parameters and uncertainties on the assumption that the model’s structure is correct. That is tolerable for flexible statistical models but not for simulations that are rigid, strongly nonlinear, tightly interconnected and often fitted to several data streams of very different size. The paper takes on the assumption that calibrating such simulations needs nothing beyond ordinary regression statistics.
The paper argues that conventional statistical calibration of complex computer simulations can give biased parameters and predictions and uncertainty estimates that are too narrow, because errors in the model’s structure are absorbed by distorted parameter values. Unbalanced data make this worse. In a test, a forest ecosystem model (BASFOR) with five deliberate structural changes was fitted to synthetic data generated by the unchanged model, and errors were far larger than the estimated uncertainty. Parameter error was about 5% when one data type had ten times fewer observations, against about 1.7% with balanced data. Giving the data-rich stream less weight improved results greatly when the structure was wrong. Fitting a flexible statistical model (a Gaussian process) to the residual errors after calibration improved predictions: error fell for gross primary production and came much closer to the estimated uncertainty for both outputs. A cheaper variant of the approach of Kennedy and O’Hagan (2001), which fits an error term during calibration, also improved parameter estimates. An attempt to correct errors inside the model’s processes did not improve inference in this setup.
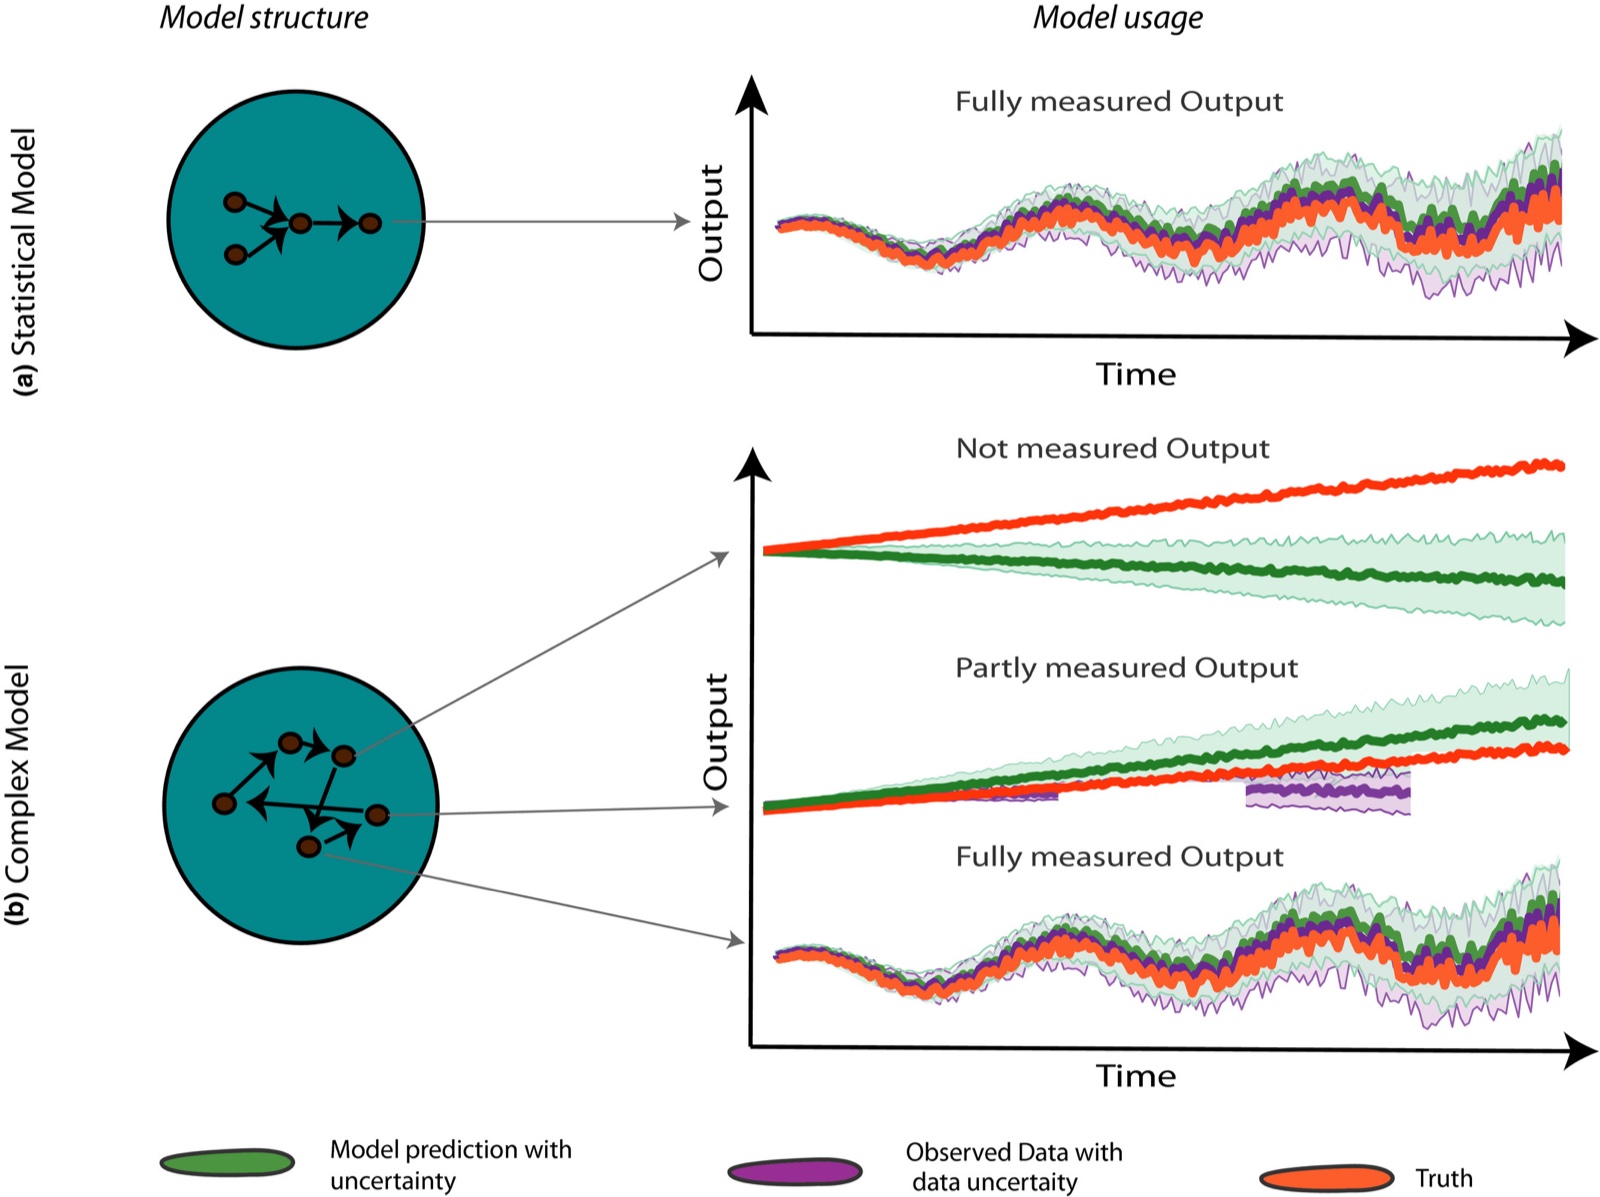
Naive calibration can therefore mislead about parameters, forecasts and their uncertainty. The paper judges that conventional methods remain adequate where random error dominates. It recommends down-weighting the larger data stream as a simple fix, and bias corrections after or during calibration for experienced modellers, at a computational cost. It stresses that these corrections are no panacea and better model structure remains preferable. Its evidence comes from one model with one error structure. Cameron et al. (2022) later examined unbalanced data using simulated (‘virtual’) data.
References
- Kennedy & O'Hagan (2001). Bayesian Calibration of Computer Models. Journal of the Royal Statistical Society Series B: Statistical Methodology 63, 425–464. doi:10.1111/1467-9868.00294
- Cameron et al. (2022). Issues in calibrating models with multiple unbalanced constraints: the significance of systematic model and data errors. Methods in Ecology and Evolution 13, 2757–2770. doi:10.1111/2041-210x.14002