The Minimum Detectable Difference (MDD) Concept for Establishing Trust in Nonsignificant Results: A Critical Review
Abstract
Current regulatory guidelines for pesticide risk assessment recommend that nonsignificant results should be complemented by the minimum detectable difference (MDD), a statistical indicator that is used to decide whether the experiment could have detected biologically relevant effects. We review the statistical theory of the MDD and perform simulations to understand its properties and error rates. Most importantly, we compare the skill of the MDD in distinguishing between true and false negatives (i.e., type II errors) with 2 alternatives: the minimum detectable effect (MDE), an indicator based on a post hoc power analysis common in medical studies; and confidence intervals (CIs). Our results demonstrate that MDD and MDE only differ in that the power of the MDD depends on the sample size. Moreover, although both MDD and MDE have some skill in distinguishing between false negatives and true absence of an effect, they do not perform as well as using CI upper bounds to establish trust in a nonsignificant result. The reason is that, unlike the CI, neither MDD nor MDE consider the estimated effect size in their calculation. We also show that MDD and MDE are no better than CIs in identifying larger effects among the false negatives. We conclude that, although MDDs are useful, CIs are preferable for deciding whether to treat a nonsignificant test result as a true negative, or for determining an upper bound for an unknown true effect.
What the paper shows and why it matters
(AI-generated)
Pesticide risk assessment has to show that a substance has no more than negligible or acceptable effects on non-target organisms. Significance tests limit only the rate of false alarms, so a nonsignificant result can come as easily from too few or too noisy data as from a true absence of an effect, especially in costly mesocosm studies. Guidelines therefore add a second filter, described by Brock et al. (2015): a nonsignificant result is trusted only if the minimum detectable difference (MDD), the effect size that would just have been significant, is below a threshold. Like the minimum detectable effect (MDE) of post hoc power analysis, the effect detected with a stated power (criticised by Hoenig and Heisey 2001), the MDD is computed without the estimated effect. Whether it can nevertheless separate true from false negatives (a real effect that was missed) was unclear.
The paper shows that, in pesticide risk assessment, the upper bound of a confidence interval separates trustworthy from untrustworthy nonsignificant results better than the minimum detectable difference (MDD), the effect size that would just have been significant. The MDD is the MDE with a power that is not controlled: a real effect equal to the MDD is significant in only about half of the experiments, probably 50–60% at sample sizes typical of risk assessment, whereas the MDE assumes a high, fixed power. In simulated count-data experiments with 3 to 10 replicates, MDD and MDE performed virtually identically once their thresholds were matched, and, whichever threshold was chosen, an upper-bound threshold gave fewer false trusts at no more false mistrusts. At a 70% threshold, for instance, over 40% of nonsignificant experiments with a real 50% reduction passed the MDD filter, against a little over 20% for the interval, at similar false mistrust. The interval uses the estimated effect; the MDD and MDE do not.
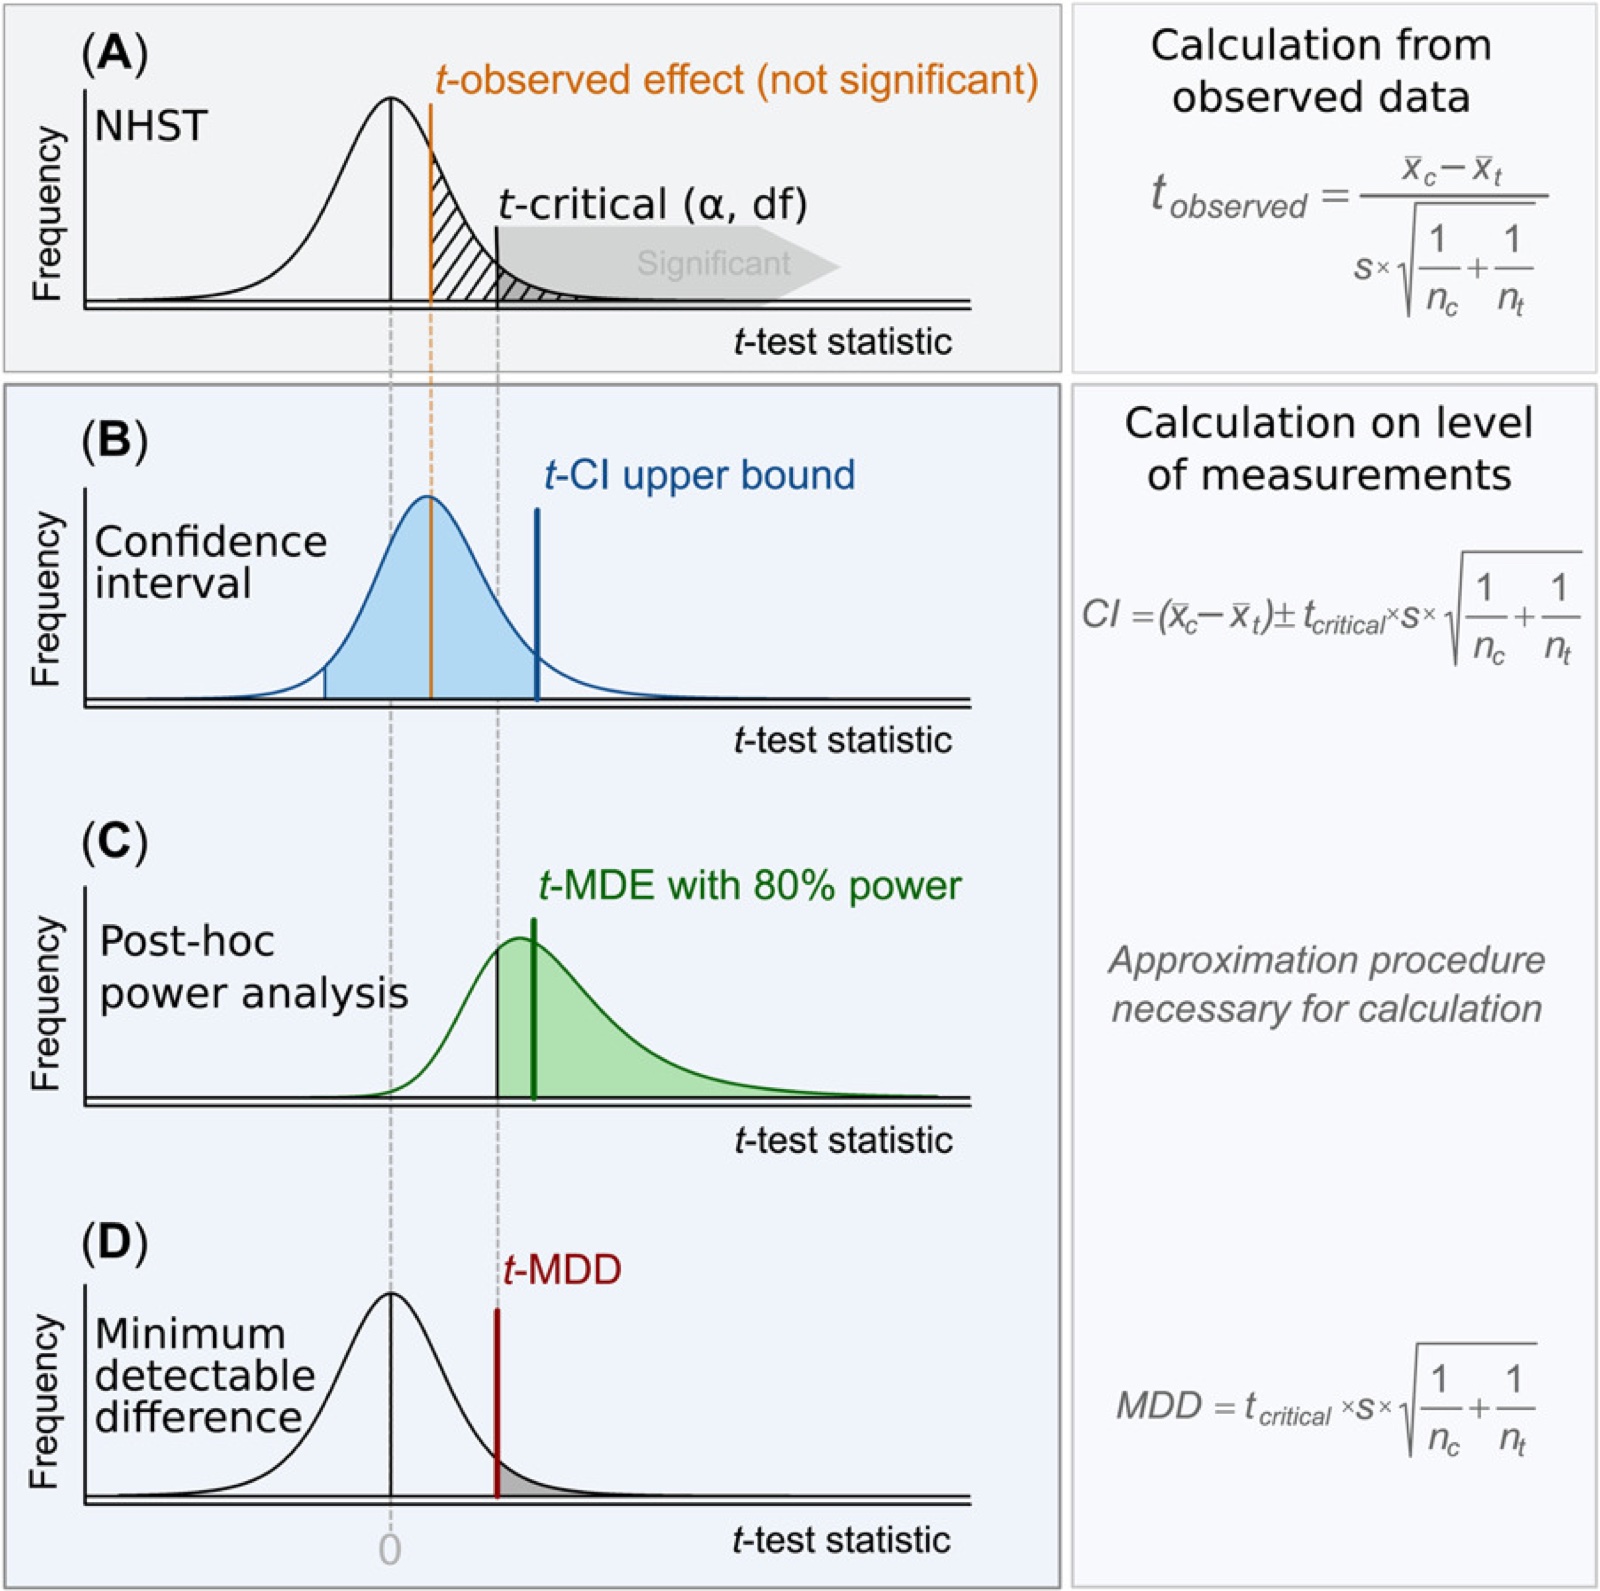
The MDD correctly states the effect that would just have been significant, but it separates true from false negatives less well than the upper confidence bound. Where risk assessment stays with significance tests, the paper recommends thresholds on the upper confidence bound. It also warns that describing the MDD as the effect that “could have been detected” can mislead. More broadly, the paper argues that regulatory decisions would be better and more transparent if they focused on estimated effects and their intervals and defined acceptable effects openly.
References
- Brock et al. (2015). The minimum detectable difference (MDD) and the interpretation of treatment-related effects of pesticides in experimental ecosystems. Environmental Science and Pollution Research 22, 1160–1174. doi:10.1007/s11356-014-3398-2
- Hoenig & Heisey (2001). The Abuse of Power: The Pervasive Fallacy of Power Calculations for Data Analysis. The American Statistician 55, 19–24. doi:10.1198/000313001300339897