Technical Note: Approximate Bayesian parameterization of a process-based tropical forest model
Abstract
Inverse parameter estimation of process-based models is a long-standing problem in many scientific disciplines. A key question for inverse parameter estimation is how to define the metric that quantifies how well model predictions fit to the data. This metric can be expressed by general cost or objective functions, but statistical inversion methods require a particular metric, the probability of observing the data given the model parameters, known as the likelihood. For technical and computational reasons, likelihoods for process-based stochastic models are usually based on general assumptions about variability in the observed data, and not on the stochasticity generated by the model. Only in recent years have new methods become available that allow the generation of likelihoods directly from stochastic simulations. Previous applications of these approximate Bayesian methods have concentrated on relatively simple models. Here, we report on the application of a simulation-based likelihood approximation for FORMIND, a parameter-rich individual-based model of tropical forest dynamics. We show that approximate Bayesian inference, based on a parametric likelihood approximation placed in a conventional Markov chain Monte Carlo (MCMC) sampler, performs well in retrieving known parameter values from virtual inventory data generated by the forest model. We analyze the results of the parameter estimation, examine its sensitivity to the choice and aggregation of model outputs and observed data (summary statistics), and demonstrate the application of this method by fitting the FORMIND model to field data from an Ecuadorian tropical forest. Finally, we discuss how this approach differs from approximate Bayesian computation (ABC), another method commonly used to generate simulation-based likelihood approximations. Our results demonstrate that simulation-based inference, which offers considerable conceptual advantages over more traditional methods for inverse parameter estimation, can be successfully applied to process-based models of high complexity. The methodology is particularly suitable for heterogeneous and complex data structures and can easily be adjusted to other model types, including most stochastic population and individual-based models. Our study therefore provides a blueprint for a fairly general approach to parameter estimation of stochastic process-based models.
What the paper shows and why it matters
(AI-generated)
Bayesian calibration of a process-based model requires the likelihood: the probability of the observations given particular parameter values. Most Bayesian calibrations of process-based ecological models have assumed how observations scatter around the model’s mean prediction, either ad hoc or from the variance in the data. Such assumptions are practical and can reflect measurement error, but are unrelated to the model’s processes, whereas many process-based models are stochastic and already predict variability, which a mechanism-based likelihood could use. Deriving such likelihoods used to be intractable; simulation-based approximations now exist but had mainly been applied to relatively simple models. The paper asks whether they work for a computationally expensive, parameter-rich model.
The paper shows that Bayesian calibration of a stochastic process-based model can use a likelihood computed from the model’s own simulations instead of assumptions about how observations scatter around its mean prediction, even for a parameter-rich, individual-based model; the model’s mechanisms must then explain both the mean and the variability of the data. The study repeatedly simulates FORMIND, a model of tropical forest dynamics, and fits a normal distribution to the simulated outputs (the “synthetic likelihood” of Wood 2010). This likelihood is used in a conventional Markov chain Monte Carlo sampler, which explores plausible parameter values. On virtual inventories generated by the model itself, where the true parameters are known, the most detailed data recovered the estimated parameters largely without bias, while coarser data summaries or more free parameters widened the uncertainty of the estimates and strengthened correlations between parameters. Fitted to tree size data from an Ecuadorian montane forest, the method considerably narrowed the prior ranges of the mortality and growth parameters and gave values broadly similar to an earlier manual calibration, with some differences in mortality.
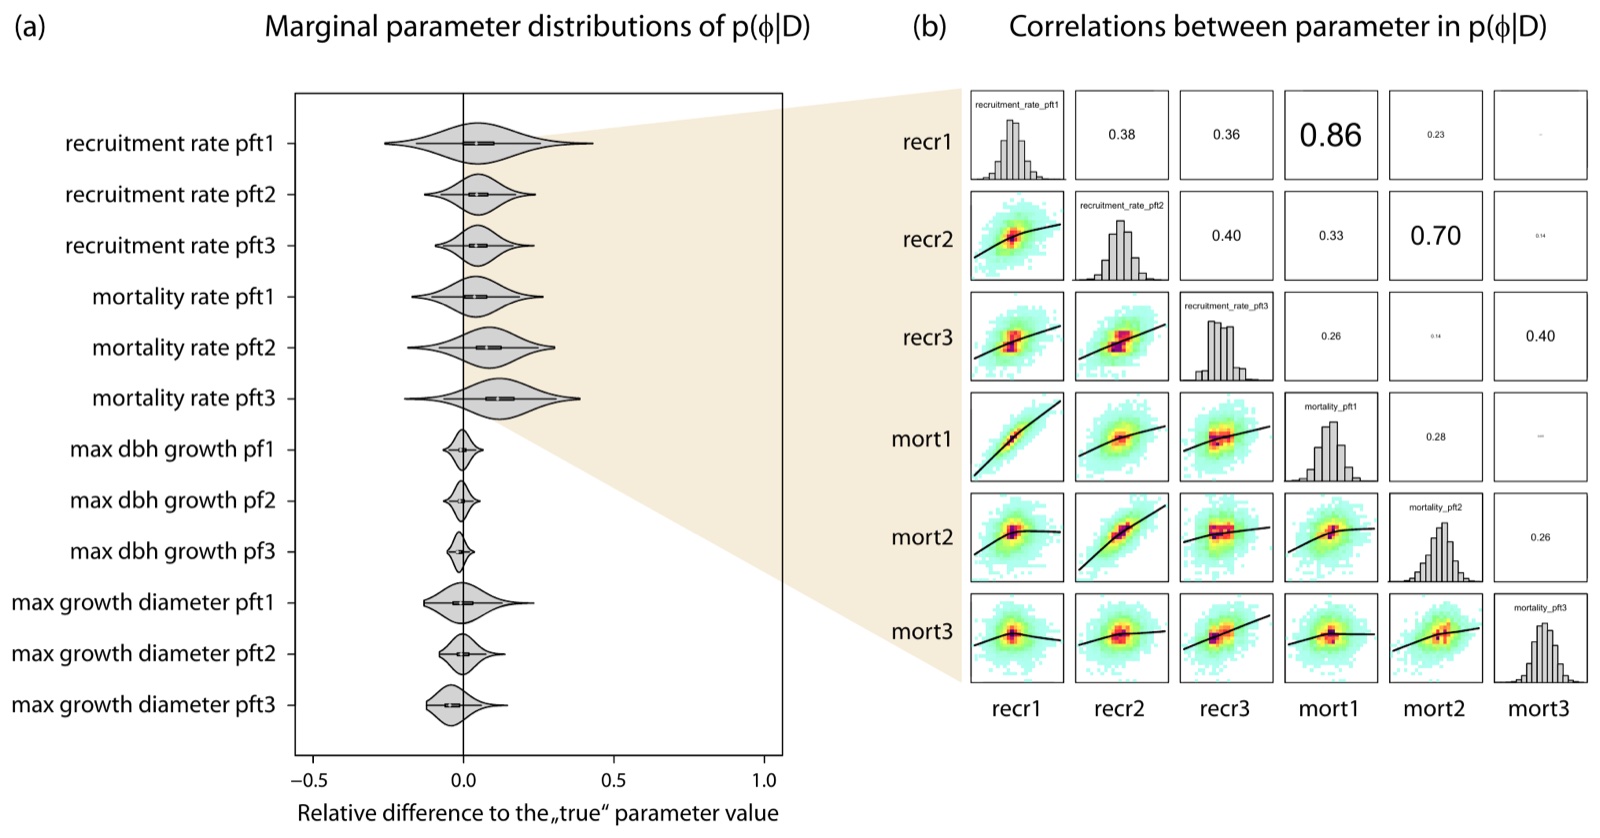
The results show that simulation-based inference is feasible for a model of this complexity, at 2–5 times the computing time of a conventional Bayesian approach, since the model has to be run to equilibrium anyway. The paper argues that such likelihoods are a promising and fairly general route for calibrating stochastic models, particularly those that are run to equilibrium. If the model contains the dominant sources of variability, the likelihood weights different kinds of data and accounts for their correlations automatically, and competing mechanistic hypotheses can be compared with formal statistical tests.
References
- Wood (2010). Statistical inference for noisy nonlinear ecological dynamic systems. Nature 466, 1102–1104. doi:10.1038/nature09319