Issues in calibrating models with multiple unbalanced constraints: the significance of systematic model and data errors
Abstract
Calibrating process‐based models using multiple constraints often improves the identifiability of model parameters, helps to avoid several errors compensating each other and produces model predictions that are more consistent with underlying processes. However, using multiple constraints can lead to predictions for some variables getting worse. This is particularly common when combining data sources with very different sample sizes. Such unbalanced model‐data fusion efforts are becoming increasingly common, for example when combining manual and automated measurements. Here we use a series of simulated virtual data experiments that aim to demonstrate and disentangle the underlying cause of issues that can occur when calibrating models with multiple unbalanced constraints in combination with systematic errors in models and data. We propose a diagnostic tool to help identify whether a calibration is failing due to these factors. We also test the utility of adding terms representing uncertainty in systematic model/data systematic error in calibrations. We show that unbalanced data by itself is not the problem—when fitting simulated data to the ‘true’ model, we can correctly recover model parameters and the true dynamics of latent variables. However, when there are systematic errors in the model or the data, we cannot recover the correct parameters. Consequently, the modelled dynamics of the low data volume variables departs significantly from the true values. We demonstrate the utility of the diagnostic tool and show that it can also be used to identify the extent of the imbalance before the calibration starts to ignore the more sparse data. Finally, we show that representing uncertainty in model structural errors and data biases in the calibration can greatly improve the model fit to low‐volume data, and improve coverage of uncertainty estimates. We conclude that the underlying issue is not one of sample size or information content per se, despite the popularity of ad hoc approaches that focus on ‘weighting’ datasets to achieve balance. Our results emphasize the importance of considering model structural deficiencies and data systematic biases in the calibration of process‐based models.
What the paper shows and why it matters
(AI-generated)
Process-based models are often calibrated against several data streams that differ greatly in volume: a few costly manual measurements are combined with large amounts of sensor or remote-sensing data. Because each observation counts as independent information in the likelihood, the large streams can swamp the sparse ones, which the model then fits poorly. A common response is to thin, aggregate or reweight the datasets. That response assumes that a poor fit reflects an imbalance in information content. The paper asks what actually causes the poor fit.
The paper argues that when process-based models are calibrated against data streams of very different size, imbalance alone is not the cause; the sparse data are fitted poorly when imbalance is combined with systematic errors in the model or the data, which the calibration absorbs into wrong parameter values. Building on an earlier study (Oberpriller et al. 2021), the paper tests this with virtual data from a deliberately simple ecosystem model, as an illustration. With a correct model and unbiased data, the true parameter values are still recovered, with wider uncertainty, even with only six observations of one variable. With a missing root pool, or soil data multiplied by 0.8, the true values are not recovered: with balanced data the fit still looks acceptable and the error stays hidden, while with unbalanced data the predictions drift away from the sparse observations. A diagnostic that needs no knowledge of the truth flags the problem: the error for the sparse variable rises as more data are added to the other streams. A linear bias-correction term in the likelihood improves the fit to the sparse data and, in general, brings them inside the predictive intervals.
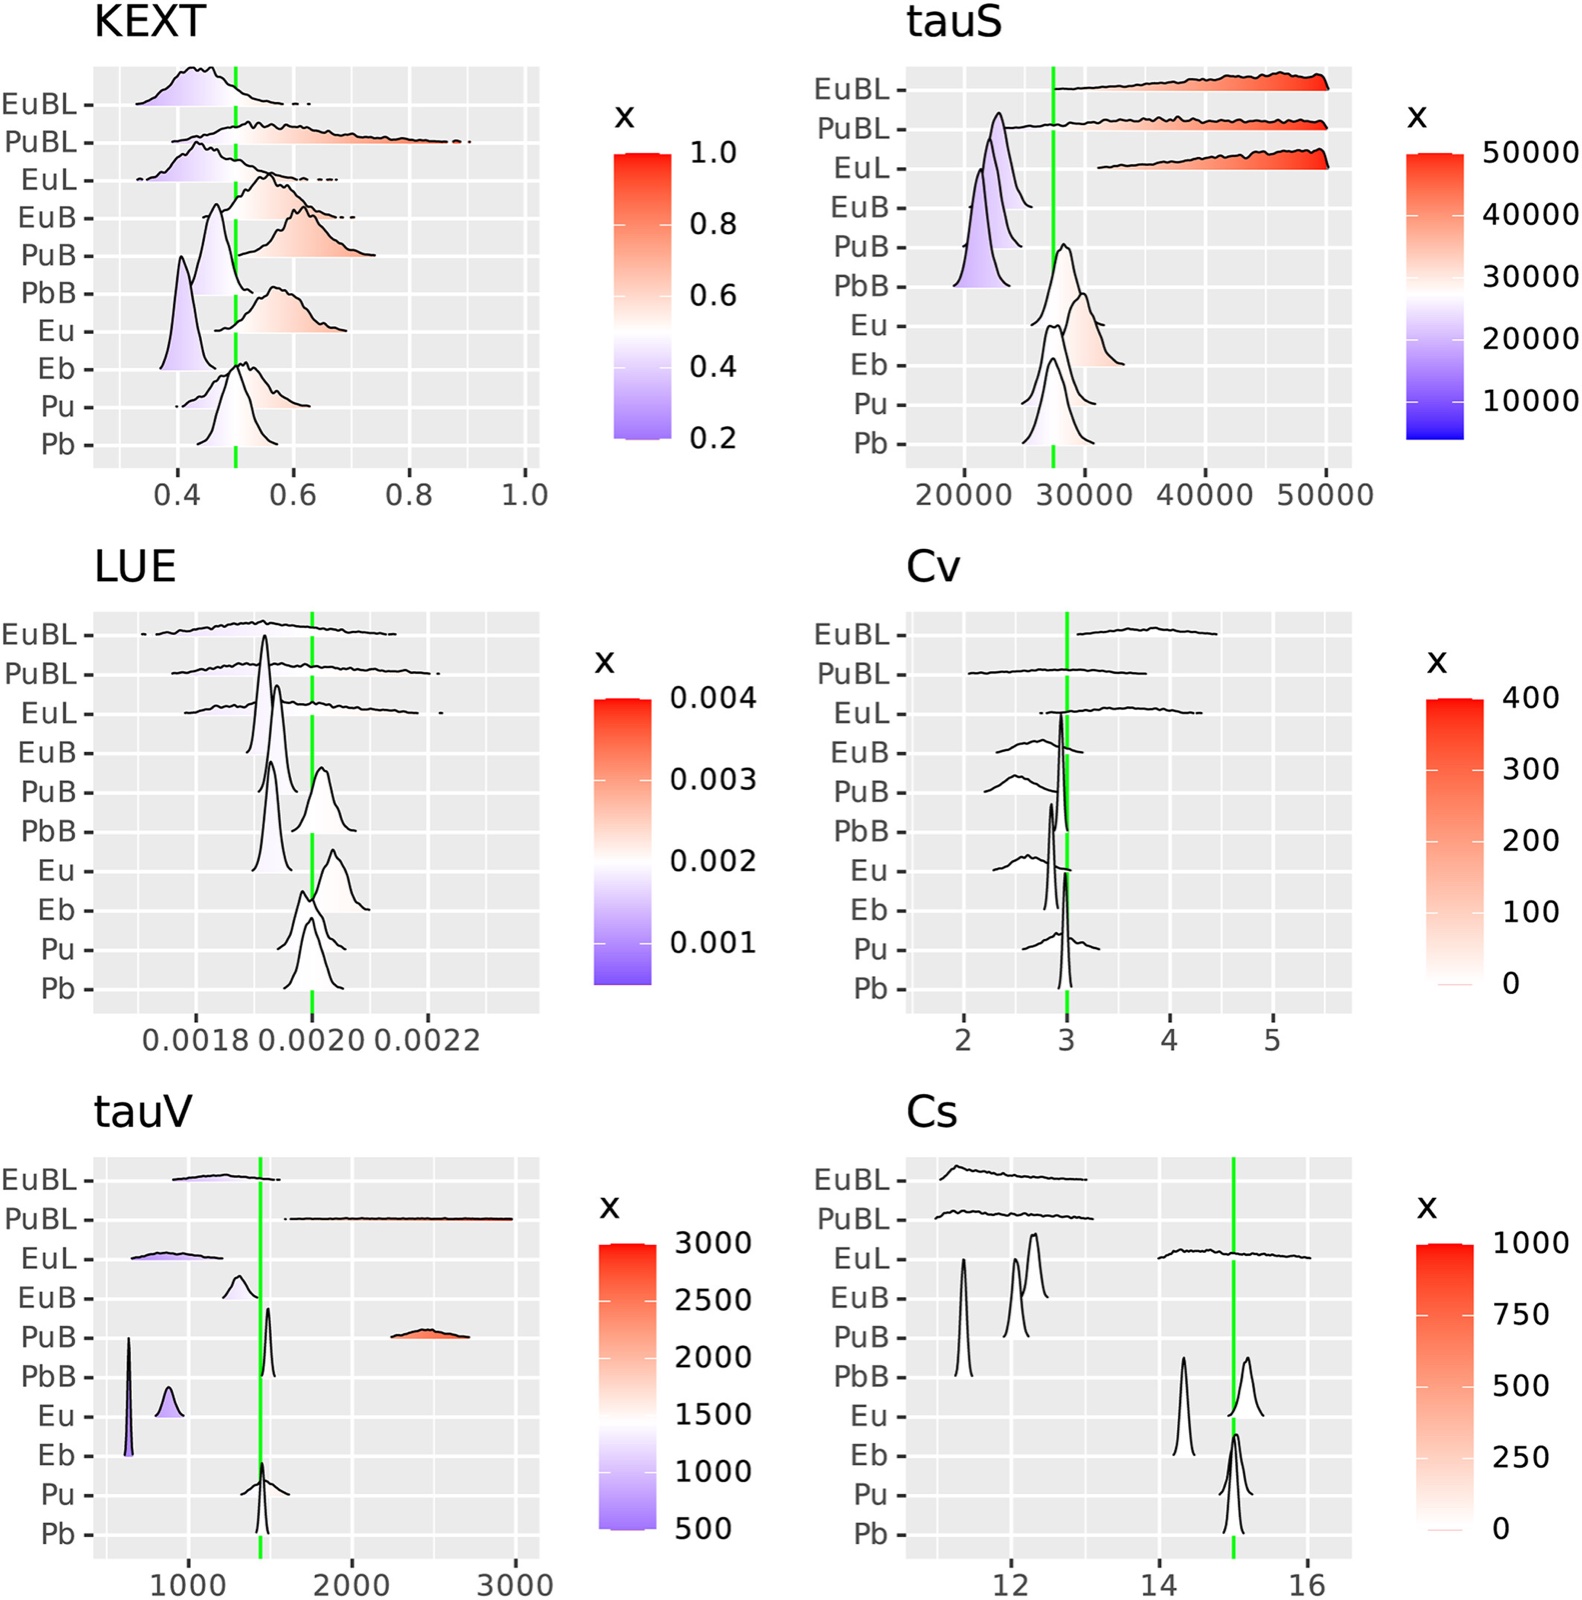
The paper concludes that reweighting treats a symptom, and advises representing model discrepancy (systematic model error) and data bias explicitly, beginning with simple terms. It states that the same hidden errors are probably even more common in single-data-stream calibrations, where they become visible only when the model is compared with other observations. Limits: one simple model with virtual data, and a correction that did not recover all true parameters. Bacour et al. (2023) cite the paper for the point that the effect of systematic model–data errors on calibration is not specific to gradient-based optimisation but also appears with random-search methods.
References
- Oberpriller et al. (2021). Towards robust statistical inference for complex computer models. Ecology Letters 24, 1251–1261. doi:10.1111/ele.13728
- Bacour et al. (2023). Assimilation of multiple datasets results in large differences in regional- to global-scale NEE and GPP budgets simulated by a terrestrial biosphere model. Biogeosciences 20, 1089–1111. doi:10.5194/bg-20-1089-2023